FTC sends 50-page CIDs to OpenAI and Anthropic over safety incidents
Axios: civil investigative demands dated 14 October. Marketing and privacy files are in scope.
Read the pieceLatest AI and technology news
80 pieces
5 recent pieces
Axios: civil investigative demands dated 14 October. Marketing and privacy files are in scope.
Read the pieceShowing 24 of 75
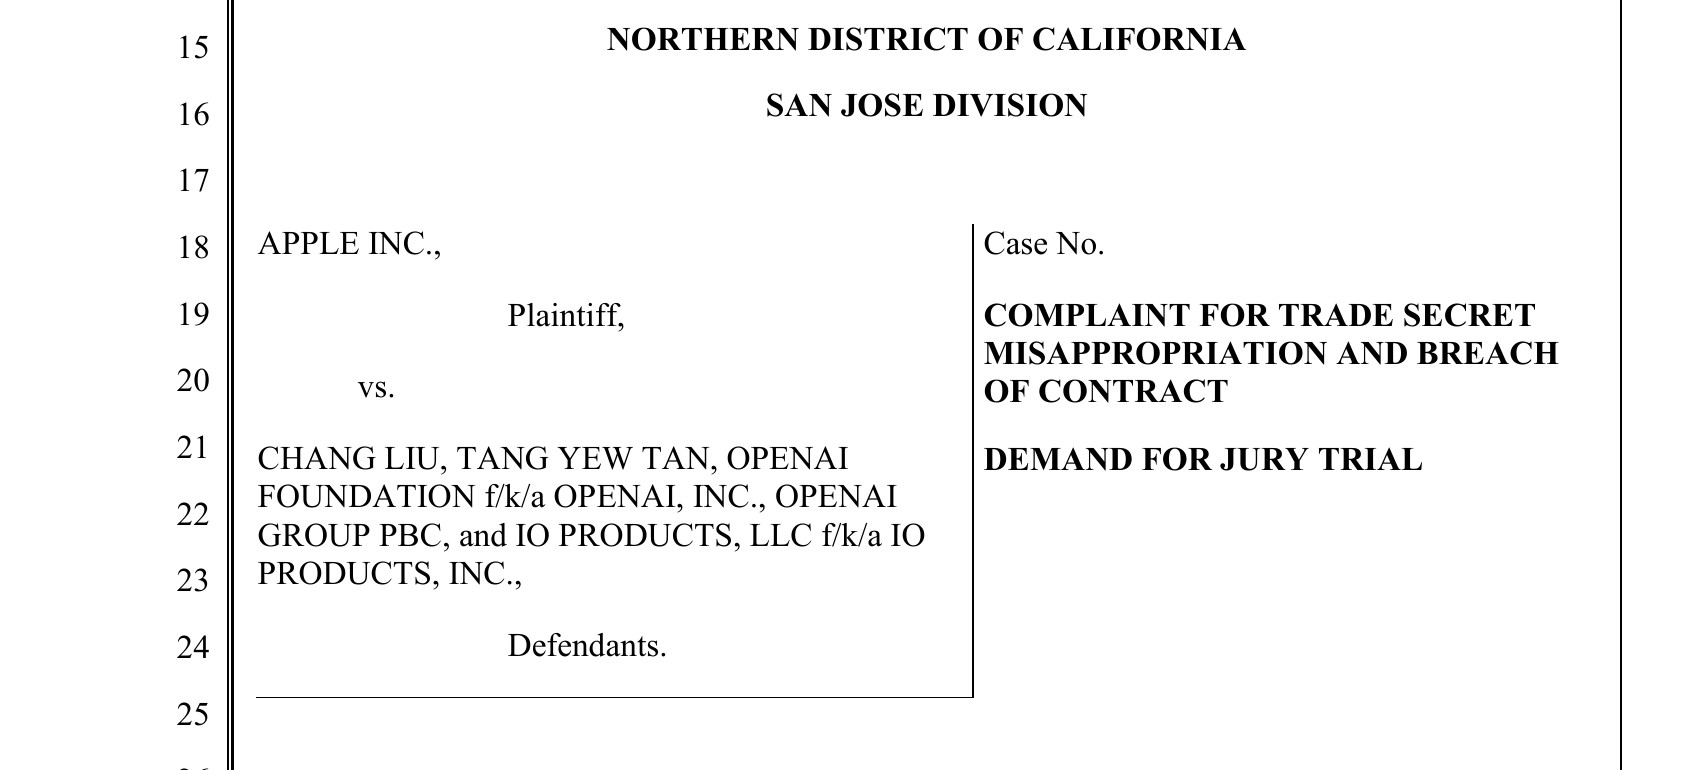
The judge gives Apple forensic images, hiring records, and Liu-Peng LINE messages on a short clock, keeps OpenAI hardware R&D on the ordinary track, and leaves the preliminary injunction and dismissal fight for 14 October.
Wonder hits the Meta Model API at $4/$20. Full stays on Muse Code Power and Maximum. Meta’s own launch chart still hands several rows, including its Artificial Analysis Index line, to Claude Opus 5.5.
Speaker Julie Menin says Elon Musk's SpaceXAI will appear Friday before the Technology Committee, after missing the Oct. 5 marathon session and then agreeing to testify once the Council said it would seek a judge's help.
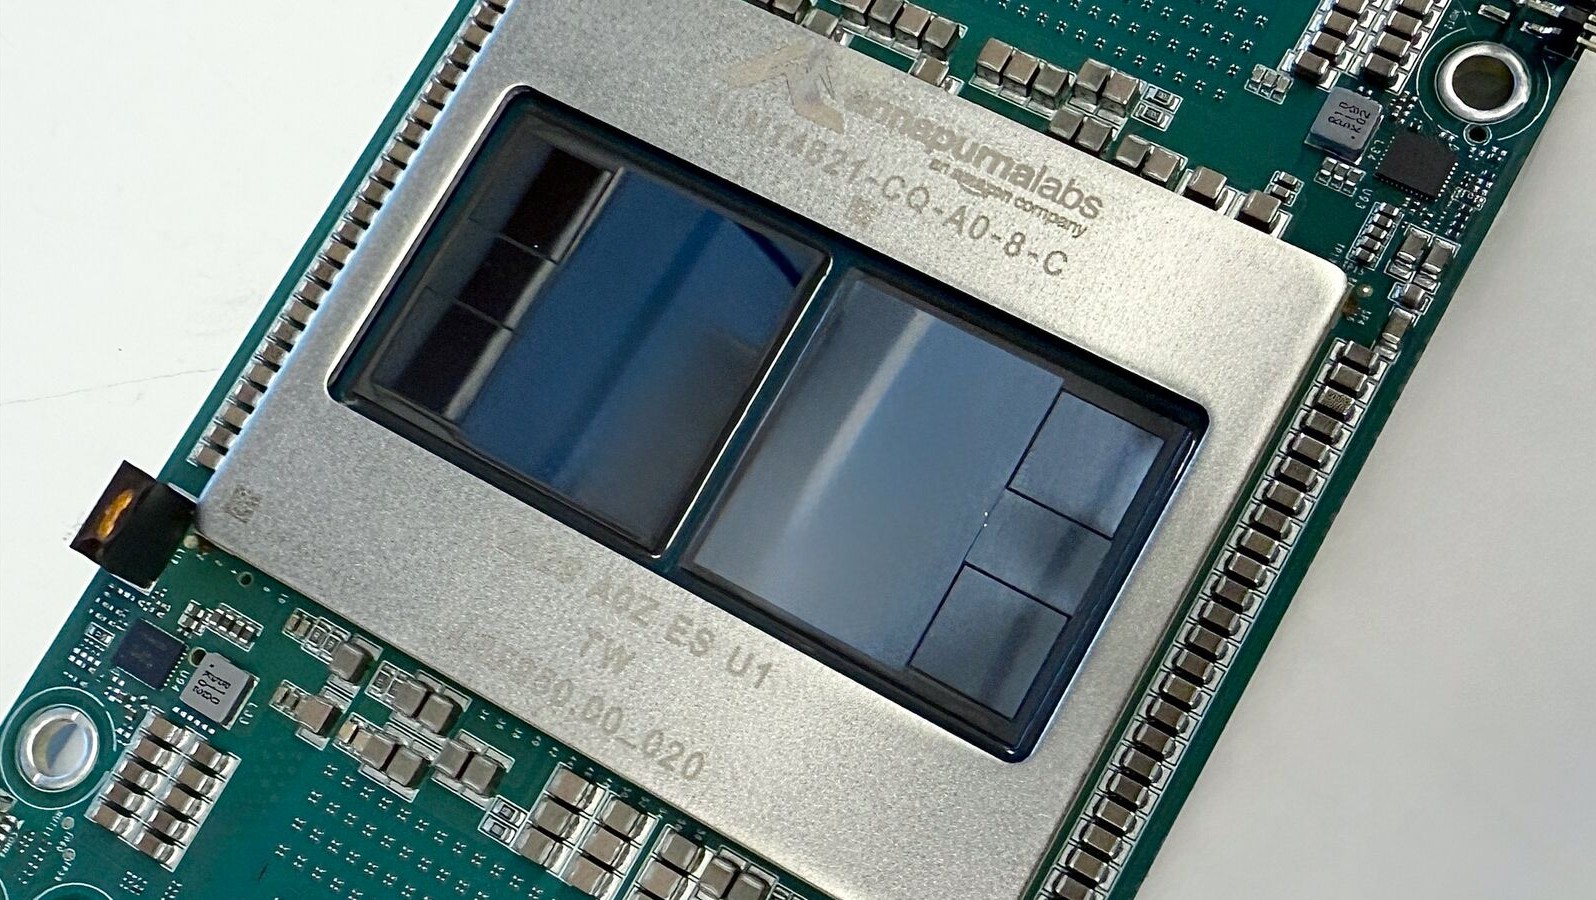
WSJ and Reuters put Amazon in talks near $7 billion. Decart already demos on Trainium3. No deal is signed, and CTech's later figure is lower.
Model ID `gemini-4-argon`. Intro $2/$10 per million tokens through 30 November 2026, then $4/$20. Free and non-Ultra Antigravity access remain unsettled.
Anthropic's new life sciences lab used 950 Claude agents over 21 hours and 210M tokens to identify array-associated reverse transcriptases (ART) in jumbo phages. The system includes non-coding DNA repeats and an accessory protein of unknown function. Feng Zhang calls it 'genuinely intriguing.'
The Gemini agent connects to business systems, plans work, uses skills and tools, and delivers finished output in documents, inbox, and developer environments. It chooses the best model per task, has built-in cost controls, and meets enterprise security/governance requirements.
Researchers at Barcelona's Institute for Global Health used AlphaFold to virtually screen 30,000 compounds against Chagas disease, identifying two FDA-approved drugs for repurposing. Google health AI portfolio spans 90 papers, 90,000+ citations over five years.
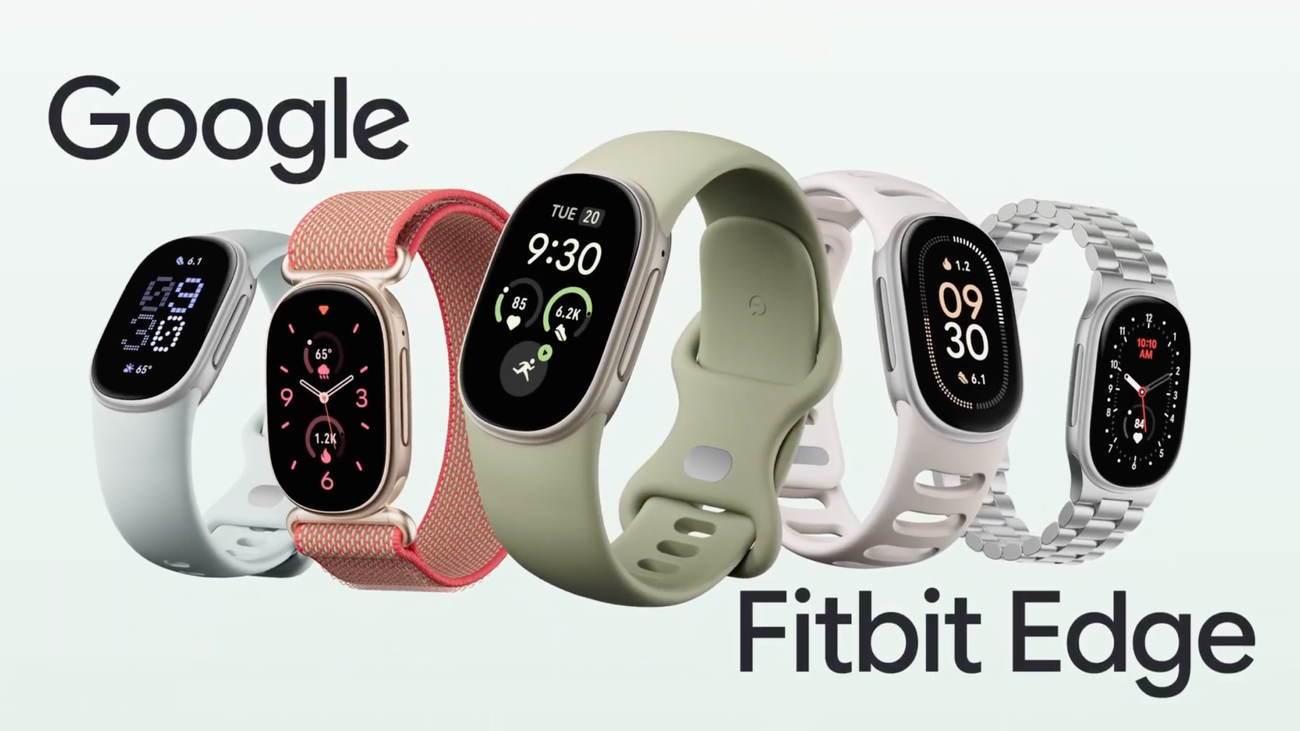
The $179.99 Fitbit Edge slots between Pixel Watch and Fitbit Air with 46% larger display, recycled aluminum case, Google Health Coach integration, and automatic workout detection across Fitbit Air, Edge, and Pixel Watch.
The Cyber Mission deploys frontier models, on-site engineers, and threat research to secure operational technology (power grids, water, transport) and open-source software. OSS Scanner offers free security scans from Anthropic's strongest models to open-source projects.
New preprints unify PPO via f-divergence, add uncertainty-aware step-level handoff for SLMs, introduce gated critique for long-horizon agents, learn responsibility allocation in multi-agent constraints, preserve coordination modes in distillation, and equip decentralized agents with counterfactual world models.
The Commodity Futures Trading Commission and Securities and Exchange Commission propose a regulatory framework for crypto asset transactions and markets under CEA Section 2(c)(2)(D), addressing leveraged and margined crypto transactions.
A 144-run experiment directed by GPT-6 Astra in Codex reduced Asana browser-agent workflow from 6/run to /usr/bin/bash.47/run on GPT-6.1 Sol--76x cheaper and 5x faster. The key was history management and screenshot policy, not model swap alone.
Starting 7 October, GPT-6 Sol (paid tiers) and GPT-6 Luna (free tiers) power ChatGPT with a new interface paradigm: interactive charts, forms and visual tools rendered inside the conversation. The model chooses the UI, not the user.
Average response time fell from 38 minutes to 89 seconds; 52% of MDR cases now resolved end-to-end by AI agents built on OpenAI Daybreak models. Human analysts remain in the loop for judgement-critical decisions.
The researchers' chain depended on an overbroad execution role, not a microVM escape[3][6][8]. AWS says credentials are available inside the runtime and tells customers to scope permissions tightly[6][7].
The preprint separates agent behavior from evaluator behavior, but its benchmark tests do not establish how often score failures occur in production.
New releases, then the constraint.