A 7B chat model for Emirati Arabic
The Technology Innovation Institute (TII) introduced Falcon-Emirati-7B in a Hugging Face blog post on 6 October 2026. TII describes it as a dialect-specialized model for understanding and generating Emirati Arabic.
TII says the model is available on its Falcon chat platform. The post links no downloadable weights. A Hugging Face search at 19:11 SGT on 6 October found no Falcon-Emirati model repository.
TII builds on Falcon-H1-Arabic 7B
TII built the model on the 7B member of its Falcon-H1-Arabic family. That family runs Mamba state space layers and Transformer attention in parallel inside each block, the post says.
TII says it chose 7B over 3B and 34B to balance quality against training and serving cost. The post credits nine authors.
Dialect fidelity is the widest gap
TII trained on three kinds of data, according to the post:
- Emirati websites and forums written natively in the dialect.
- Modern Standard Arabic material about Emirati culture, heritage and social norms.
- Synthetic Emirati text generated under glossaries, dictionaries and style rules.
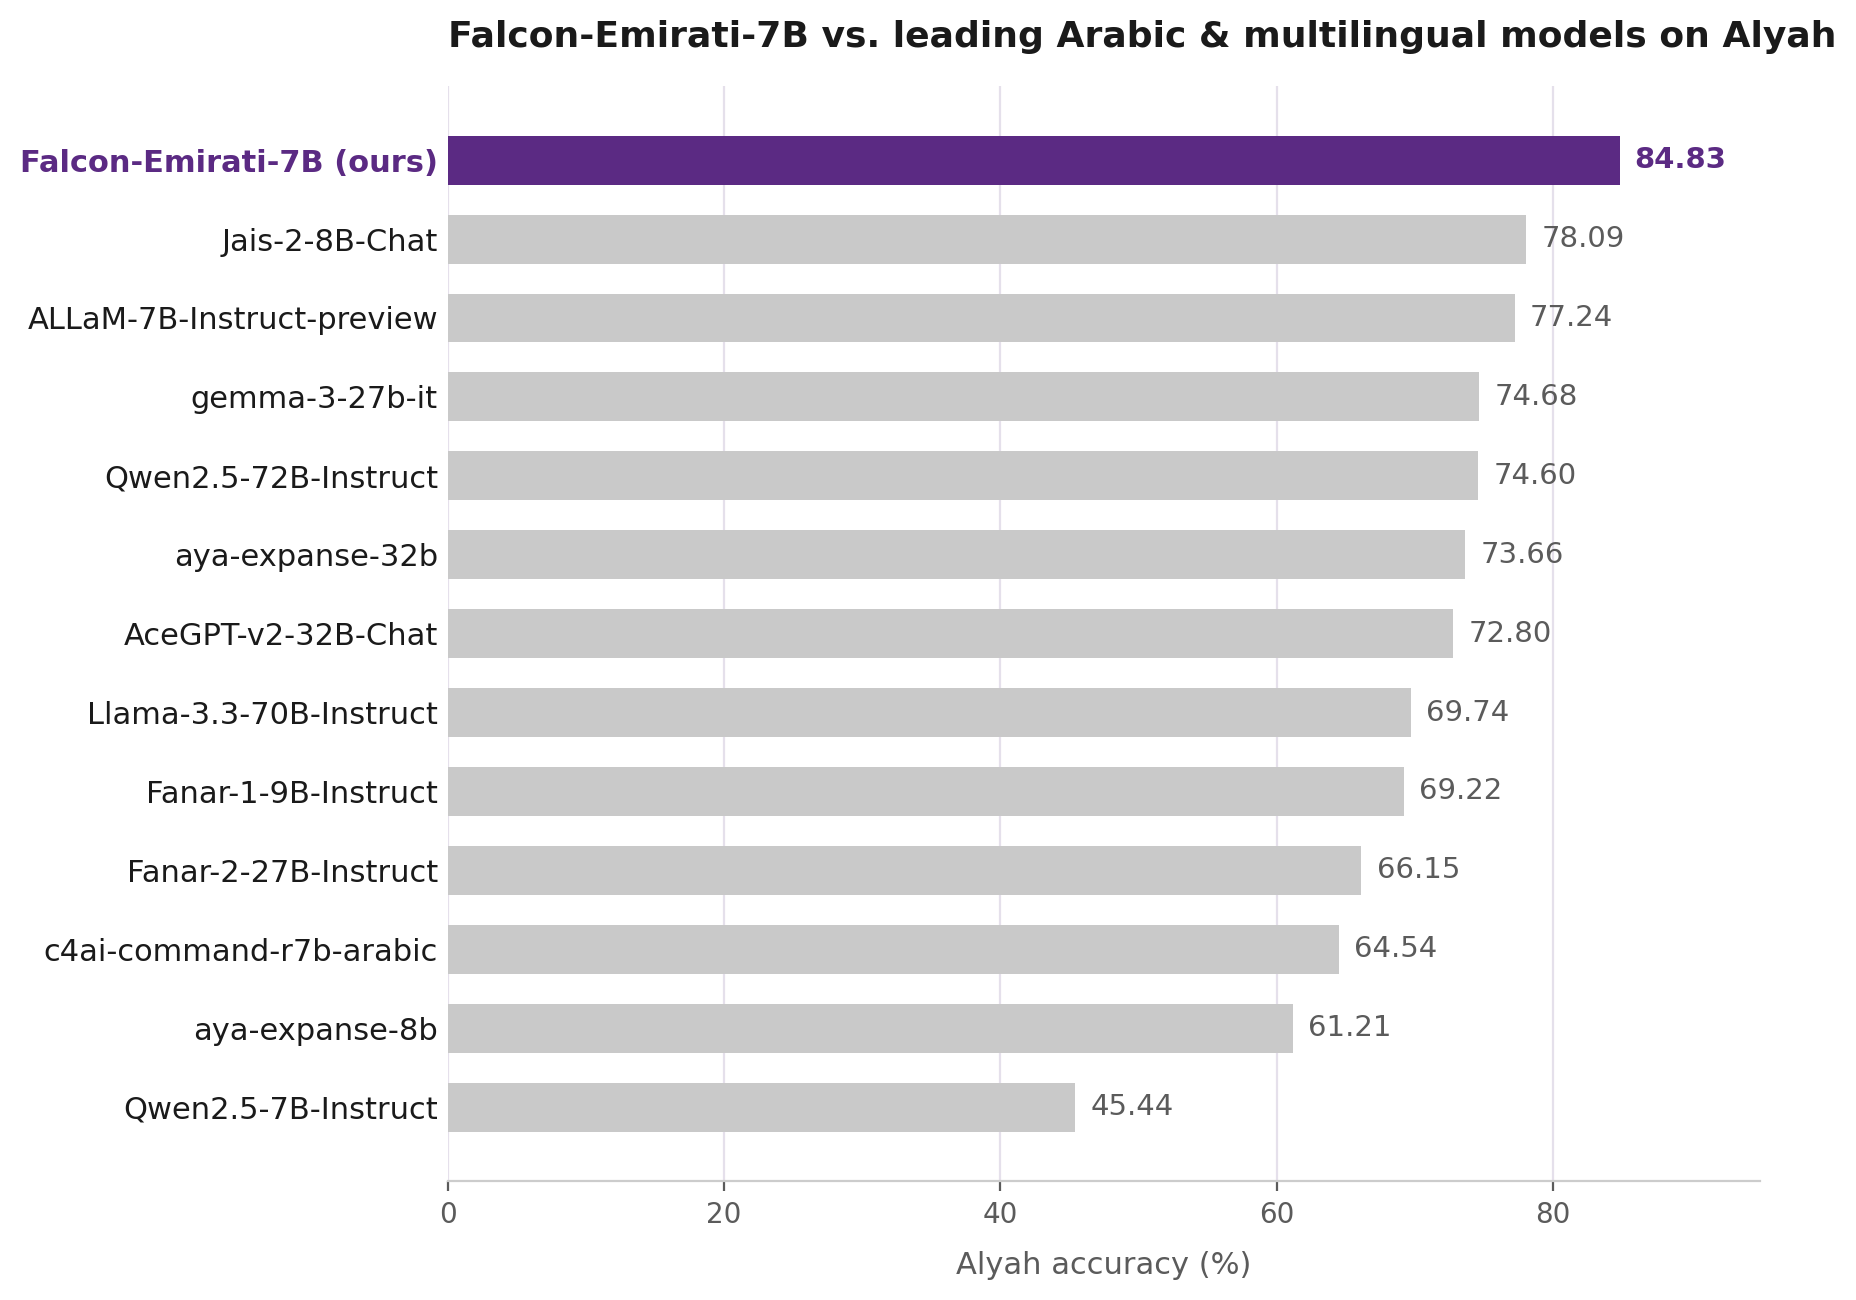
TII reports 84.83% on Alyah, a 1,173-question multiple-choice benchmark of Emirati dialect and culture. The chart excludes Falcon-H1-Arabic models because Falcon-Emirati is built on them.
The table shows the top five of the 13 models in TII's chart.
| Model | Alyah accuracy (%), per TII |
|---|---|
| Falcon-Emirati-7B | 84.83 |
| Jais-2-8B-Chat | 78.09 |
| ALLaM-7B-Instruct-preview | 77.24 |
| gemma-3-27b-it | 74.68 |
| Qwen2.5-72B-Instruct | 74.60 |
TII also had Gemini 3.7 Flash judge open-ended answers to the same questions. On whether answers came back in Emirati dialect, Falcon-Emirati scored 0.52 in partial credit. ALLaM scored 0.05, gemma-3-27b-it 0.03 and Jais-2-8B-Chat 0.02, and Fanar-2-27B-Instruct scored effectively zero.
On 283 UAE scenarios from the ArabCulture-Dialogue benchmark, TII reports 85.57% for Falcon-Emirati and 83.39% for ALLaM-7B.
TII grades its own benchmark
- All scores come from TII. TII released Alyah with the community, and the open-ended answers were graded by Google's Gemini 3.7 Flash.
- In blind pairwise judging, Falcon-Emirati narrowly lost Greetings and Daily Expressions to Jais-2-8B-Chat, 0.46 to 0.54. It tied ALLaM in that category.
- TII says Fanar-2-27B-Instruct declined to answer 26.2% of the time, against under 5% for every other model.
- TII warns the model can reflect training data biases and get rare expressions wrong. It recommends evaluating it before sensitive, official or high-stakes use.
- The post gives no license, API or pricing details.
Test it on your own Emirati prompts
- Teams serving Emirati users can try the model in Falcon chat and compare it with their current model on real prompts.
- Evaluation teams can run the public Alyah dataset against their own models.
- Anyone planning production use should wait for weights or an API and a license from TII.
Aleph Alpha's Kolibri-1 is another model built around specific languages, German and English. See Aleph Alpha Kolibri-1 opens 78B German and English MoE weights under Apache 2.0, with 3.46B active parameters.