Beam has 501B parameters with 23B active
Reflection published Introducing Beam: Reflection's 501B open-weight model on a page dated 5 October 2026. Reflection calls Beam its first open-weight model.
The post describes a sparse mixture of experts with 501 billion total parameters and 23 billion active per token. Reflection says it built Beam for coding, reasoning and agentic work.
The weights are not out yet, and a Hugging Face search at 19:11 SGT on 6 October found no Beam repository. Reflection says it will release the weights, technical report, model card and developer artifacts later this month, under an Apache 2.0 license.
Reflection runs a waitlist before launch
Reflection says Beam is undergoing final red-teaming and evaluations. Early access goes to a select group of users through a waitlist.
The company says it will launch Beam with distribution partners and integrations with open source libraries and harnesses. The post names no partner.
Reflection calls Beam the first model in a series and says it is already training the next one.
Long reinforcement learning on GB300 clusters
The post gives these training figures:
- Pretraining used 23.8 trillion tokens from the web, public sources and proprietary licensed datasets.
- Pretraining ran in under four weeks on 6,144 NVIDIA GB300 NVL72 GPUs.
- The reinforcement learning run used 10.5K NVIDIA GB300 GPUs for four weeks and generated more than 100 million rollouts.
- Rollouts reached a maximum context of 256K tokens, and midtraining extends the effective context to 1M tokens.
- Beam is text-only, and a reasoning effort setting trades response length against performance.
Reflection's benchmark table compares Beam with seven other models. Selected rows follow, with "not reported" where the table has no score.
| Benchmark | Beam | Inkling | Nemotron 3 Ultra | GLM 5.3 | Kimi K3 |
|---|---|---|---|---|---|
| Terminal Bench v2.1 | 80.1 | 63.8 | 56.4 | 88.2 | 88.3 |
| DeepSWE v1.1 | 44.4 | not reported | not reported | 61.0 | 68.0 |
| SWE Bench Pro v2-Hard | 77.2 | 56.9 | not reported | 84.3 | 88.2 |
| HLE without tools | 36.2 | 29.7 | 26.7 | 42.3 | 46.9 |
| GPQA Diamond | 90.5 | 87.2 | 87 | 91.7 | 93.5 |
| MCP Atlas | 78.7 | 76.0 | 63.1 | 84.2 | 82.3 |
| AA-LCR | 79.3 | 77.3 | 79.3 | 79.7 | 88.7 |
The full table also lists GLM 5.2, Qwen 3.8 Max and DeepSeek V4.1 Flash. On Terminal Bench v2.1, GLM 5.2 scores 81.0 and DeepSeek V4.1 Flash scores 90.6.
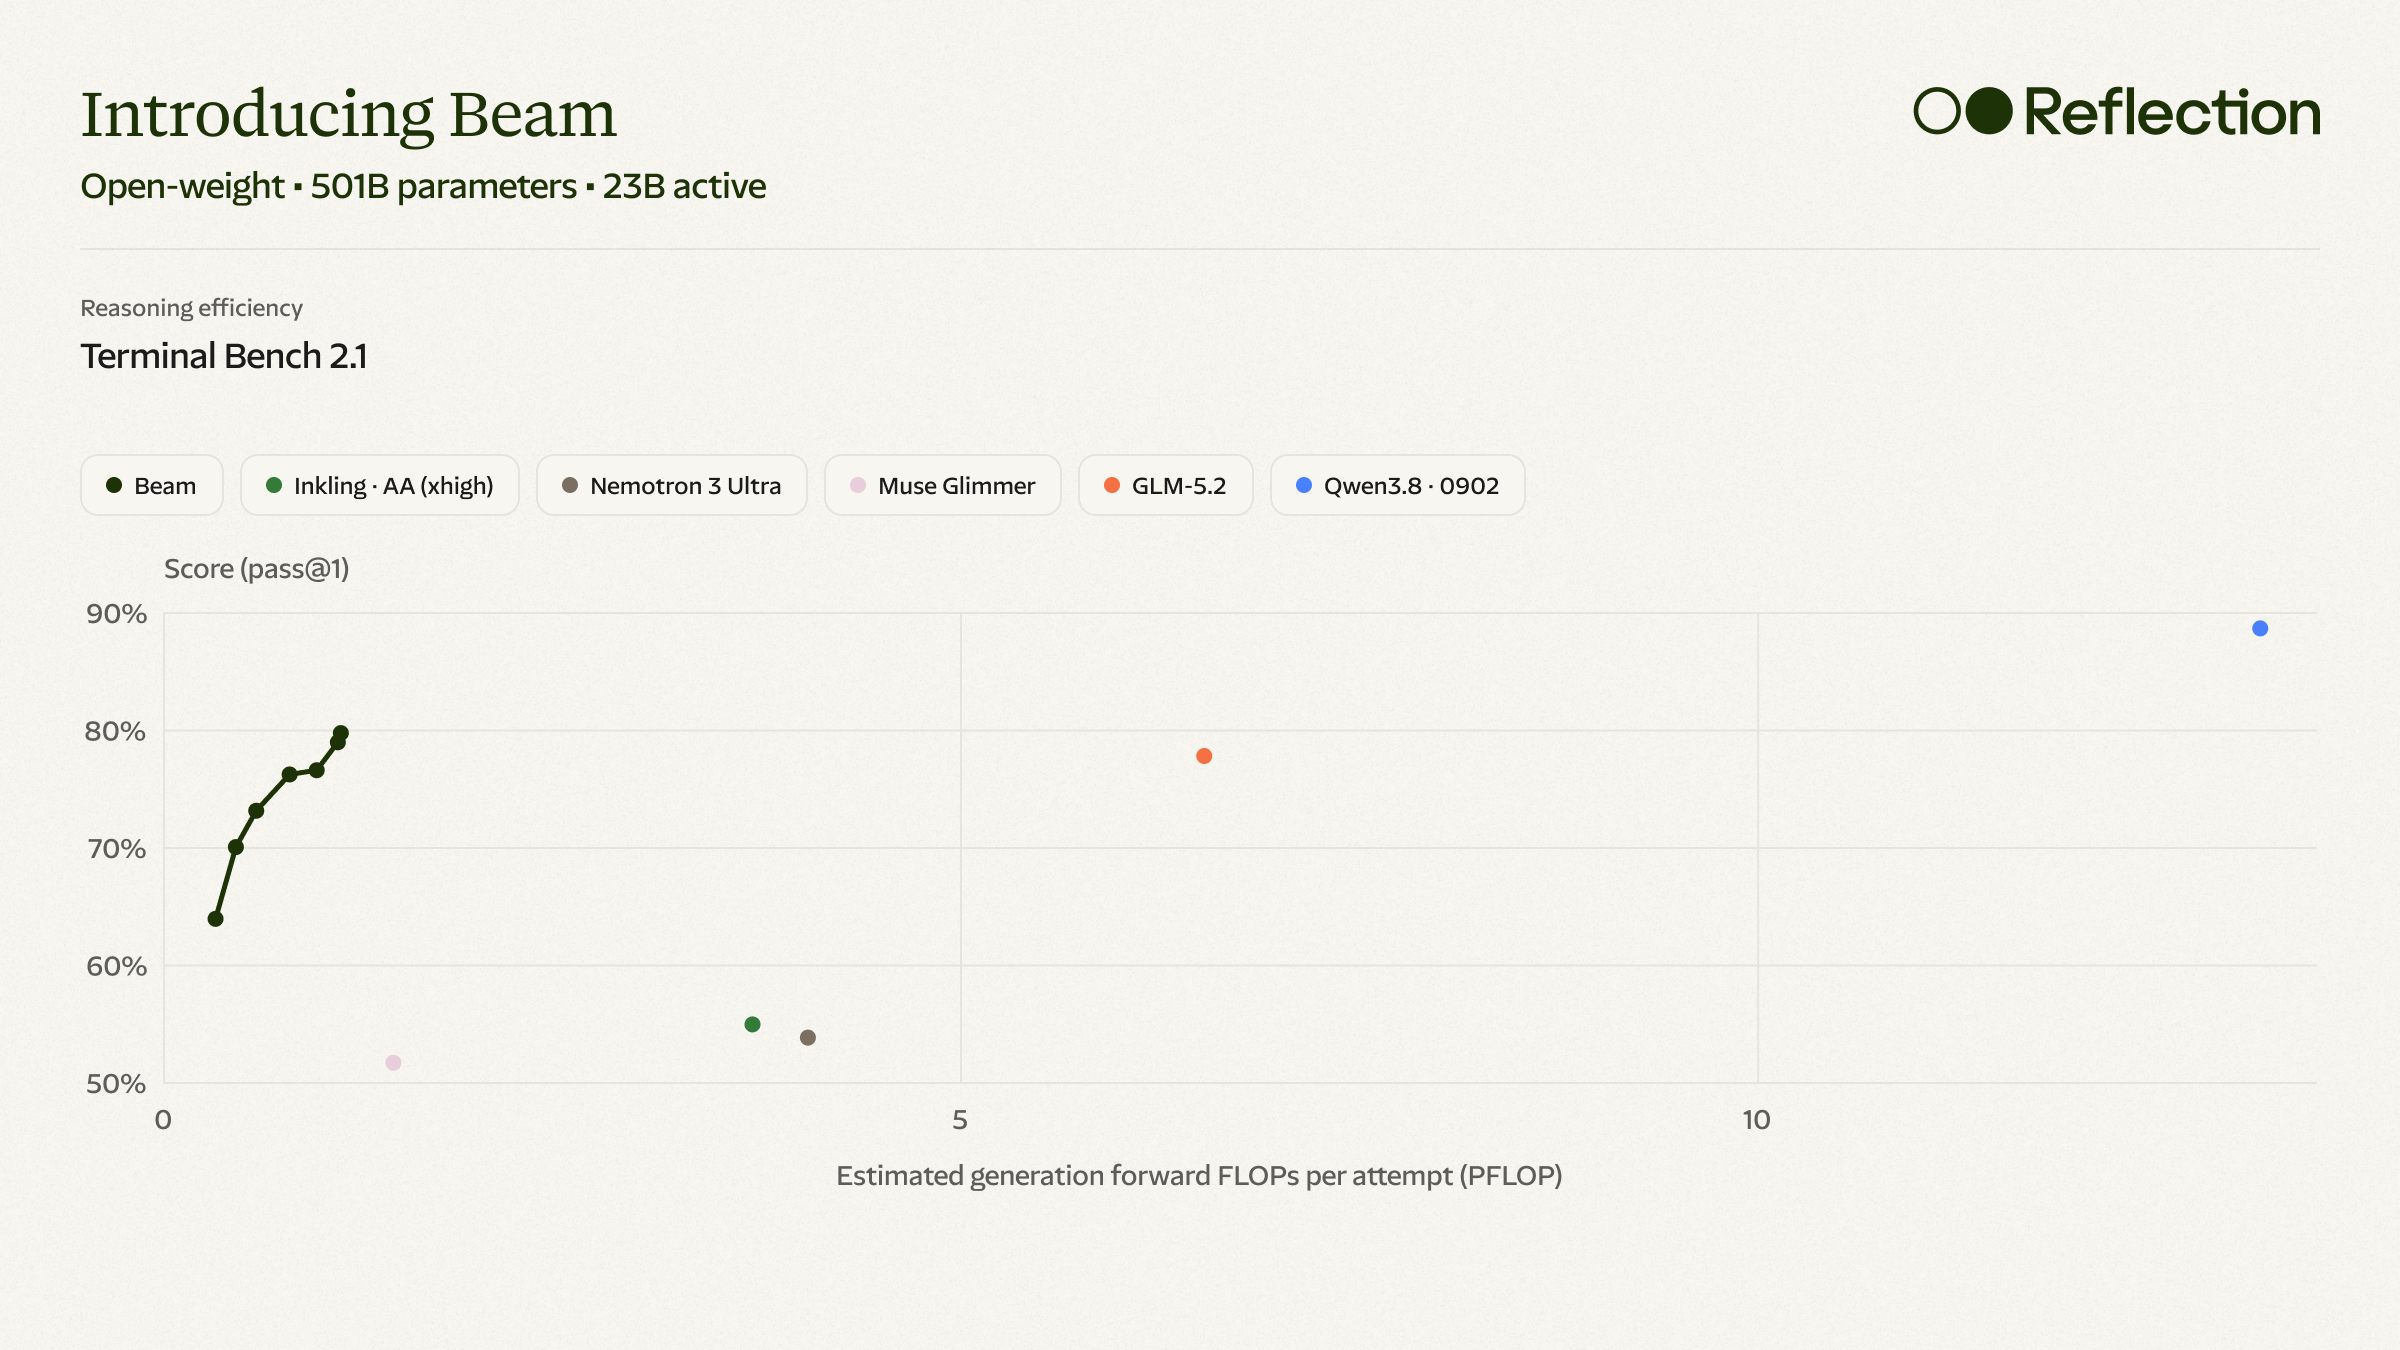
Reflection says Beam scores comparably to GLM-5.2 on advanced reasoning benchmarks while using three to four times less inference compute.
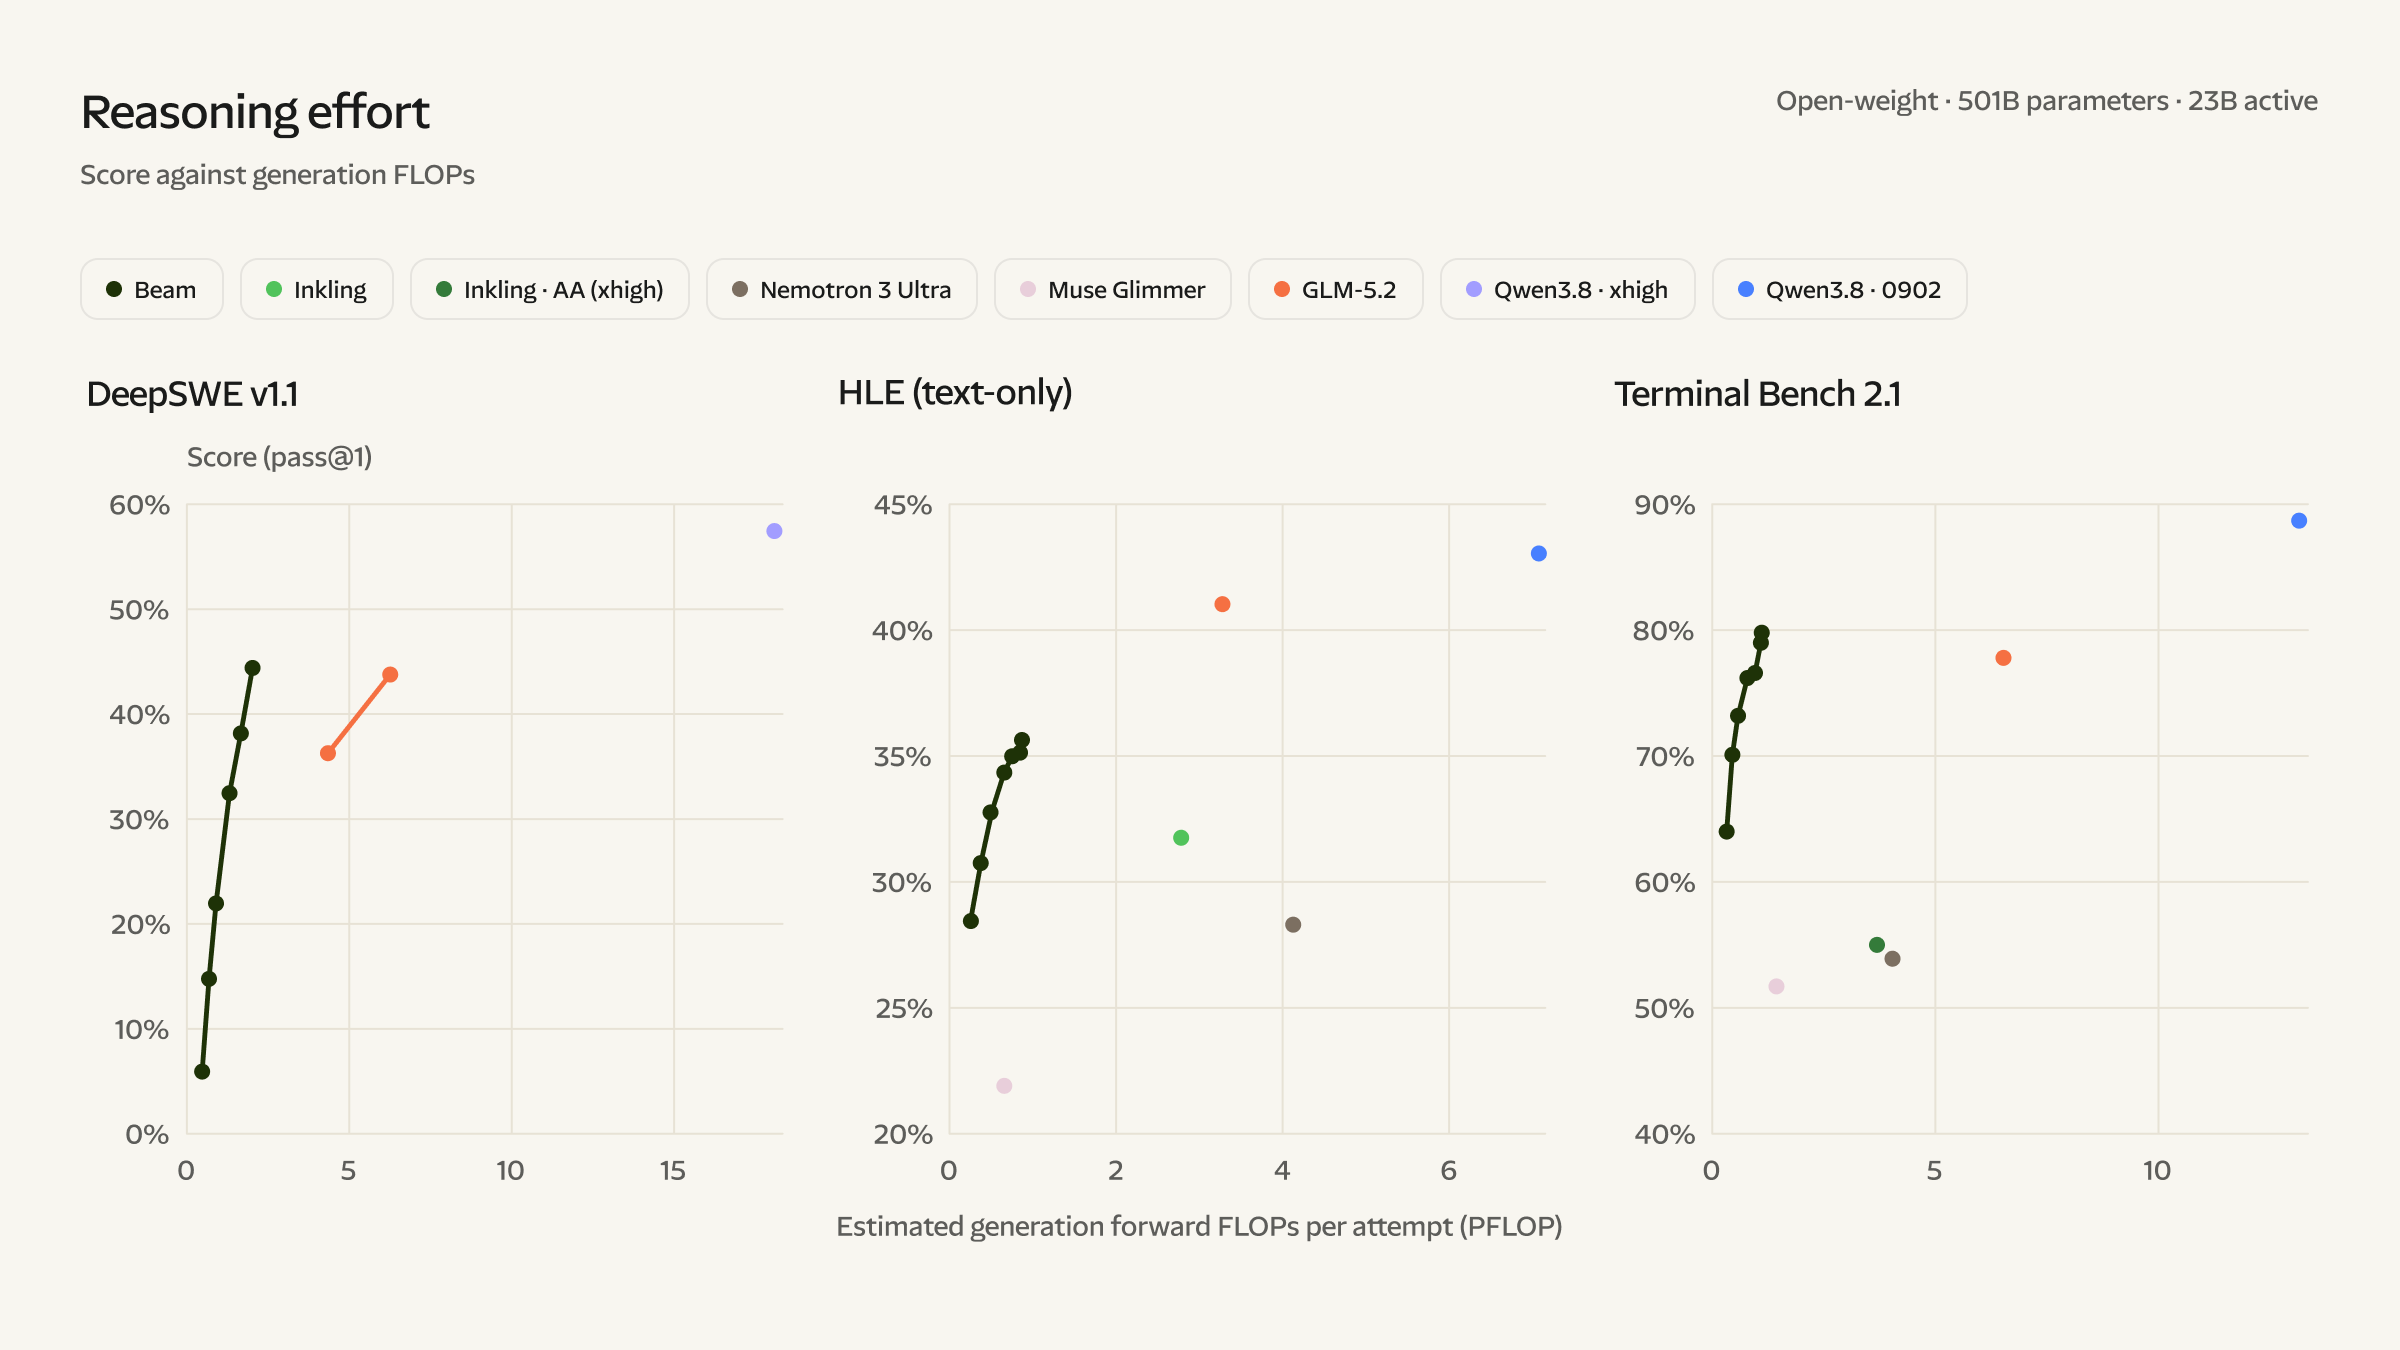 Beam's scores at each reasoning effort setting, plotted against estimated compute per attempt.
Source: Reflection, Introducing Beam, 5 October 2026
No weights, model card or report yet
- Every Beam score comes from Reflection, and The Frontier found no independent test.
- A caption on Reflection's efficiency figure says rival scores come from Artificial Analysis and DataCurve.
- Reflection estimates compute from active parameters and mean generated tokens. It says the estimates exclude prompt prefill and serving overhead, so they only approximate compute.
- By our reading of Reflection's coding table, Beam trails GLM 5.3, Kimi K3 and DeepSeek V4.1 Flash on every row where they have scores.
- The license is a promise until the weights ship. No hardware requirements, quantized formats or prices appear in the post.
- Reflection says it will publish safety evaluation results in the technical report.
Join the waitlist and wait for the card
- Teams that want to test early can join the waitlist on Reflection's page.
- Hold any self-hosting plan until the model card lists memory needs. By our arithmetic, 501 billion parameters at 16 bits come to about 1 TB of weights.
- When the weights land, check that the LICENSE file says Apache 2.0, as the post promises.
- Run your own coding and agent evals against GLM 5.3 and Kimi K3 before you switch.
Aleph Alpha released Kolibri-1 with open weights on Hugging Face. See Aleph Alpha Kolibri-1 opens 78B German and English MoE weights under Apache 2.0, with 3.46B active parameters.
For security findings on one of Beam's comparison models, see Anthropic says Z.ai GLM-5.3 brings Mythos-class cyber skills with weak open-weight safeguards.