Twelve CPAs take simplified APEX tasks
Mercor published its human baseline study post on 1 October 2026. The study hired 12 junior accountants to complete simplified versions of tasks from Mercor's APEX-Accounting benchmark.
All participants were licensed CPAs. They averaged about five and a half years of accounting experience.
Each person completed four month-end close scenarios. They had to dig through a company's working files, do the math and deliver a results table.
Mercor Research, with Ramp on the parent benchmark
Mercor ran the human baseline study. The related APEX-Accounting benchmark was built with Ramp, per Mercor's research line.
The blog says Mercor designed the study to measure AI augmentation. Models alone scored perfectly on the simplified tasks, so there was no room to measure uplift. The write-up focuses on unassisted humans against AI.
About 37% for people, "ace" for models
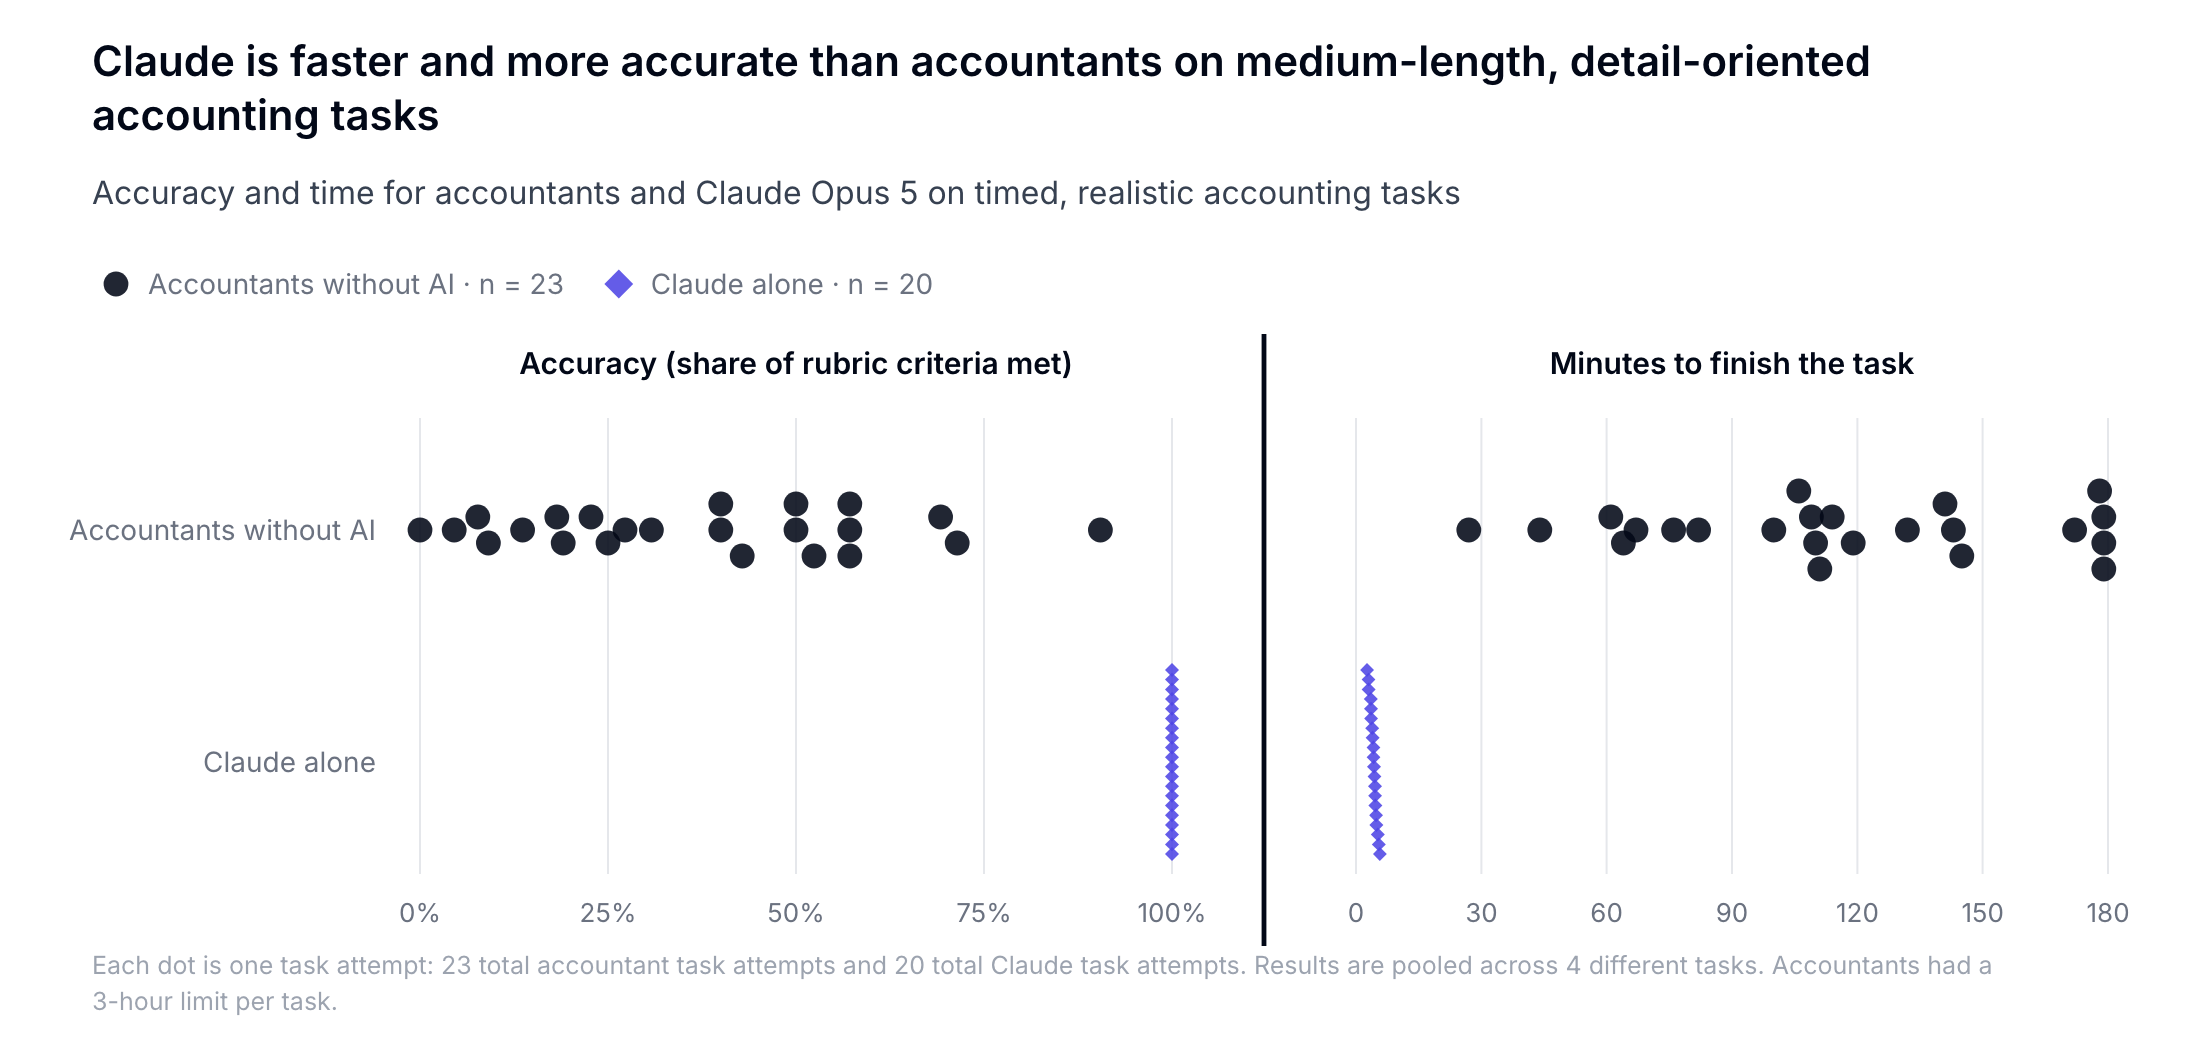
Participants averaged about 37% of grading criteria without AI. Mercor says that matches what task authors expected for juniors (about 30%) and sits below the mid-level expectation of about 55%.
Eighteen months ago, Mercor says, the best AI models still fell short of that human average. Today, it says models ace the same tasks and are more than an order of magnitude cheaper per criterion than humans at the compared wage.
The Frontier found no independent replication. Exact per-model scores and dollar figures are not printed in the blog prose The Frontier extracted.
A narrow slice of the job
Mercor says the results do not mean accountants are replaceable. The tasks stress detail-oriented instruction following, file search and precise arithmetic.
The setting removed coworkers and accumulated job context. Client communication and asking the right questions were not measured.
Task authors told Mercor the traps in the files are realistic, and that the conditions and scoring drove the low human scores.
Accounting leads and benchmark readers
- Finance leaders should read the 37% figure as a score on Mercor's simplified rubric. Treat it as a task score only.
- Benchmark users should ask for human baselines when a board claims models match "real work."
- Model vendors citing APEX-Accounting should keep the full 160-task board separate from this four-task human study.