Luna's price, with a 100,000-token catch
Claude Haiku 5.5 now costs the same as OpenAI's GPT-6 Luna for short prompts. Anthropic reports that it leads Luna on every test both models share. Prompts over 100,000 tokens pay five times the short rate.
Anthropic released the model on 7 October US time with a launch post and a 144-page system card. Its Claude account posted the launch at 02:01 SGT on 8 October. It calls Haiku 5.5 "the cheapest, fastest, and most capable small model we've ever released".
Per million tokens, Haiku 5.5 costs $0.10 input and $0.50 output for prompts up to 100,000 tokens. Above that line it costs $0.50 and $2.50. Haiku 4.5 costs $1 and $5. OpenAI's pricing page lists gpt-6-luna at $0.10 and $0.50 at short context, and $0.20 and $0.75 at long context.
Anthropic also halved Sonnet 5.5 cache reads to $0.10 per million tokens, nine days after that model launched. See Anthropic releases Claude Sonnet 5.5 on 28 September at unchanged Sonnet 5 prices.
Claude Code already defaults to Haiku 5.5
Some users get the new model without changing any code. Version 2.1.293 of the Claude Code changelog calls Haiku 5.5 "now the default Haiku model on the Anthropic API".
The model page lists Haiku 5.5 on the Claude API, Amazon Bedrock, Google Cloud, Microsoft Foundry and Claude Platform on AWS. Its model ID is claude-haiku-5-5, with no date suffix. The context window grows to 1M tokens, up from 200,000 on Haiku 4.5.
The deprecations table still lists claude-haiku-4-5-20251001 as active, with retirement no sooner than 15 October 2026. The same page promises at least 60 days' notice before a public model retires. Sonnet 4.5 got 61 days when Anthropic deprecated it on 30 September. See Claude Sonnet 4.5 deprecated: Anthropic retires claude-sonnet-4-5-20250929 on the Claude API on 30 November.
Anthropic says monthly API credits arrive this week: $100 for Max 5x, $200 for Max 20x and up to $500 pooled for Team.
Two of Anthropic's four cost charts favour Sonnet 5.5
The system card says the table below uses Haiku 5.5 at max effort. The API default is medium. At medium, Haiku 5.5 scored 1277 on GDPval-AA, against 1620 at max.
| Test, as Anthropic reports it | Haiku 5.5 | Haiku 4.5 | GPT-6 Luna | Sonnet 5.5 |
|---|---|---|---|---|
| GDPval-AA v2.1, Elo | 1620 | 735 | 1437 | 1840 |
| OSWorld 2.1 offline subset | 72.4% | 15.7% | 48.9% | 83.9% |
| Terminal-Bench 4.0 | 39.2% | 0.0% | 16.4% | 70.6% |
| FrontierCode 1.1 Main | 46.4% | Not reported | 42.4% | 52.1% at xhigh |
| Chartography, no tools | 46.4% | 6.4% | 29.1% | 61.6% |
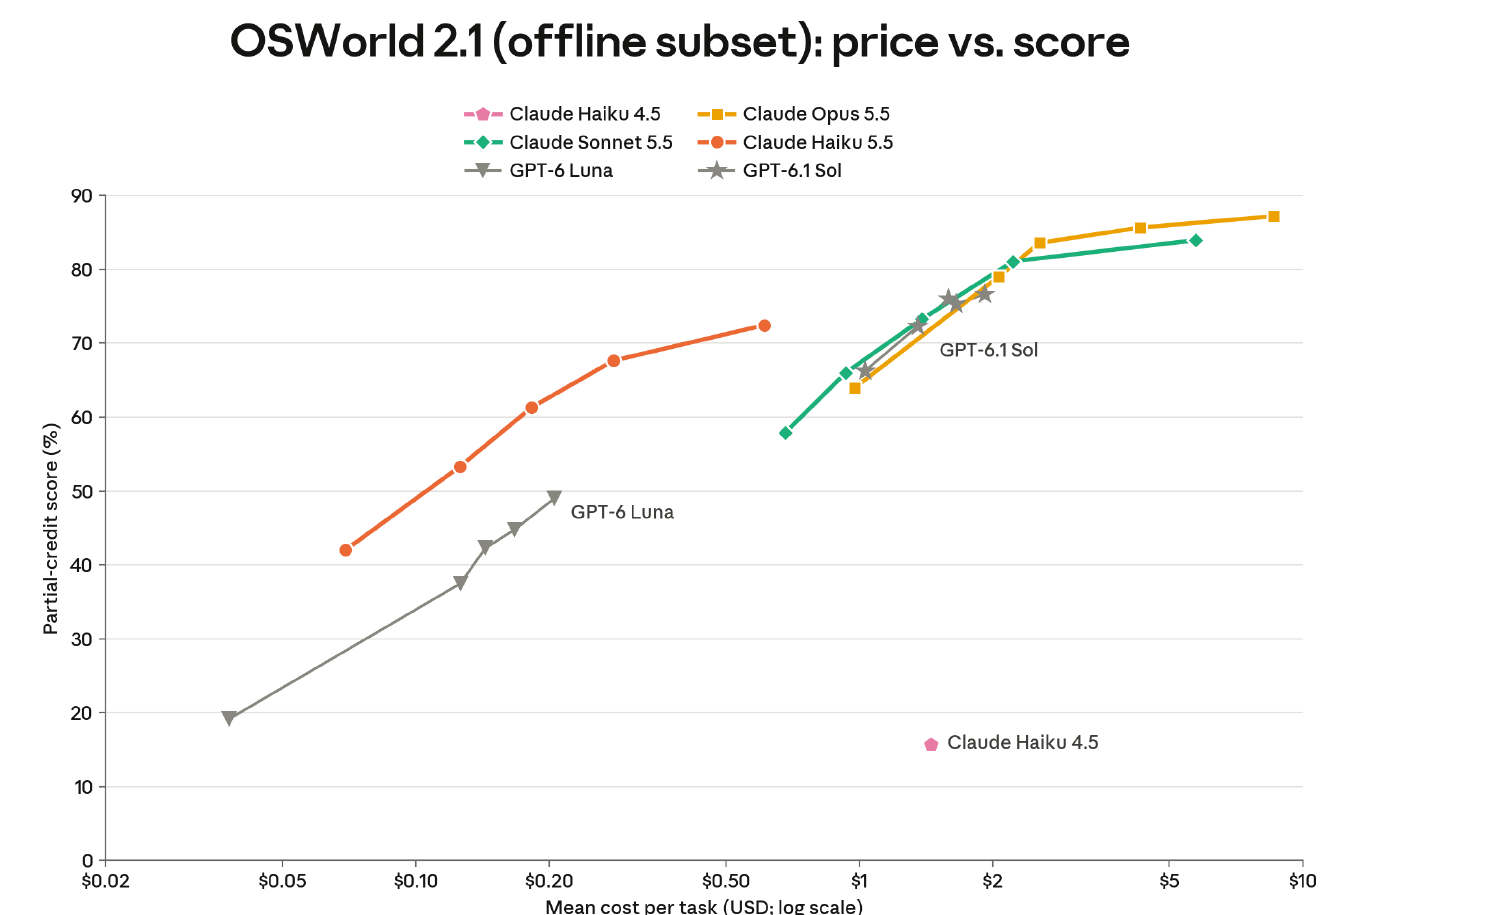
The post also plots score against cost per attempt at each effort level. On its Humanity's Last Exam and Terminal-Bench 4.0 charts, Sonnet 5.5 at high effort scores above Haiku 5.5 at max and costs less.
- On Humanity's Last Exam without tools, the chart shows Sonnet 5.5 at 47.9% for about $0.08 and Haiku 5.5 at 45.9% for about $0.21.
- On Terminal-Bench 4.0, it shows Sonnet 5.5 at 43.0% for $1.46 and Haiku 5.5 at 39.2% for $2.64.
- On GDPval-AA, Haiku 5.5 at high effort scores 1420 and Luna at max scores 1437, both at about $0.09 a task.
- On OSWorld, Haiku 5.5 at high effort scores 61.3% for about $0.18, above Luna at max with 48.9% for about $0.21.
The system card says its Sonnet costs for Humanity's Last Exam assume a perfect cache hit rate. Its Haiku costs use list prices on recorded usage. The post itself says Sonnet 5.5 and Opus 5.5 "remain better choices" for complex agentic coding.
No independent board lists Haiku 5.5 yet
Every score above comes from Anthropic's runs or from evaluators it names. The Frontier checked 11 public boards between 02:30 and 02:33 SGT on 8 October, and none listed Haiku 5.5.
They were Artificial Analysis, LMArena, Vals AI, OpenRouter, the Terminal-Bench board, Cognition's FrontierCode, Surge's Chartography, Proximal's FrontierSWE, Scale SEAL, Epoch AI and Design Arena.
The system card says Artificial Analysis ran GDPval-AA and AA-Briefcase independently. Its public GDPval-AA board did not show those results, and its Haiku 5.5 model page returned a 404. On that board, 1620 would sit below GLM-5.3-Flash at 1647 and above DeepSeek V4.1 Flash at 1600. Neither model appears in Anthropic's launch table.
The Luna figures Anthropic uses match the public boards: 1437 on GDPval-AA, 29.1% on Surge's Chartography board and 16.36% on the Terminal-Bench board. Anthropic ran its own Terminal-Bench trials in Claude Code with no internet access. The public board shows Sonnet 5.5 at 61.82%, where Anthropic reports 70.6%.
The system card says Haiku 5.5 "usually did not reach the level of Claude Sonnet 5.5". It also reports that Haiku 5.5 over-refused more than any other model in Anthropic's automated behavioural audit.
Its safety classifiers have no fallback model. On Terminal-Bench, 12 of 660 trials stopped when a classifier flagged a request, and all of them failed. Anthropic calls Haiku 5.5 its fastest model at standard speed, and no independent speed figure was public at the check.
Recount tokens before moving off Haiku 4.5
- Count prompts again with
claude-haiku-5-5. The migration guide says the same text produces about 30% more tokens than on Haiku 4.5. - At that rate, a short prompt costs about 87% less to send than on Haiku 4.5, and a prompt over 100,000 tokens about 35% less.
- Log how many requests cross 100,000 tokens. Anthropic says about 90% of Haiku 4.5 requests stayed under that line.
- Remove manual thinking budgets, assistant prefills and non-default sampling values. The guide says each returns a 400 error.
- Handle
stop_reason: "refusal"in your client, since the classifiers have no server-side fallback. - Plan Priority Tier capacity separately. The guide says Priority Tier does not support Haiku 5.5.
- Test at the effort level you will run, because Anthropic's headline scores use max.